stationops
Kubernetes Fleet Observability & Autonomous SRE Self-Healing Engine
Distributed cloud operations platform and autonomous incident remediation mesh processing 120M+ monthly DAG workflows, detecting memory leaks in 30ms and reducing critical MTTR by 84%.
Distributed execution across AWS, GCP & Azure fleets
Reduced downtime from 4 hours to under 38 minutes
Autonomous eBPF kernel probes inspecting pod state
Continuous FinOps resource right-sizing and spot allocation
Global SaaS enterprises managing thousands of microservices across multi-region Kubernetes clusters were paralyzed by incident fatigue. On-call Site Reliability Engineers (SREs) received upwards of 400 alerts every night, the majority of which were cascading symptoms of silent pod memory leaks or cross-region network latency spikes.
Mean Time to Resolution (MTTR) for critical severity-1 incidents averaged over 4 hours. By the time engineers correlated logs, identified root causes, and manually triggered rollbacks, enterprise customers had experienced catastrophic service degradation resulting in contractual SLA penalty breaches.
Core Workstreams Executed:
- Engineered kernel-level eBPF telemetry probes to capture non-intrusive runtime latency, socket errors, and memory allocation traces.
- Designed autonomous self-healing runbooks powered by Temporal state machine DAGs to remediate common infrastructure anomalies without human paging.
- Constructed an automated canary analysis and zero-downtime rollback controller integrated directly into Kubernetes deployment controllers.
- Built the StationOps real-time dark cloud operations dashboard visualizing multi-cloud cluster topology, flamegraphs, and incident triage streams.
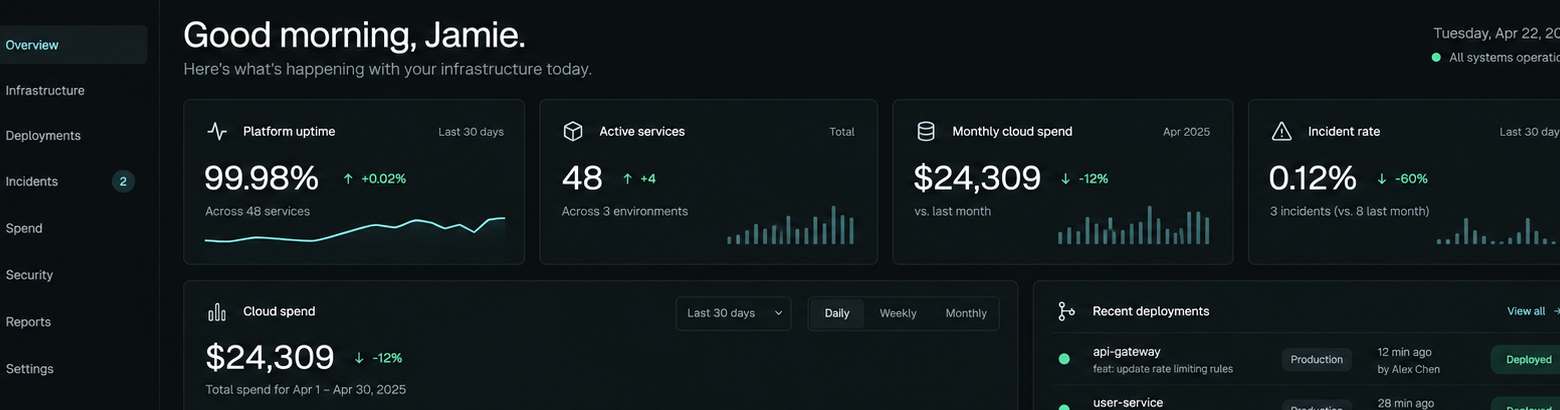
Cluster Fleet Telemetry & Self-Healing Execution Rates
The master StationOps control room provides infrastructure engineering teams with live visibility across global Kubernetes fleets. SREs can track live pod health, automated self-healing events, and cloud resource consumption.
- check_circle Live monitoring of 120M+ monthly DAG workflows running across 14 cloud regions
- check_circle 91.4% autonomous resolution rate for infrastructure incidents without human paging
- check_circle Continuous FinOps right-sizing metrics identifying idle over-provisioned CPU and RAM
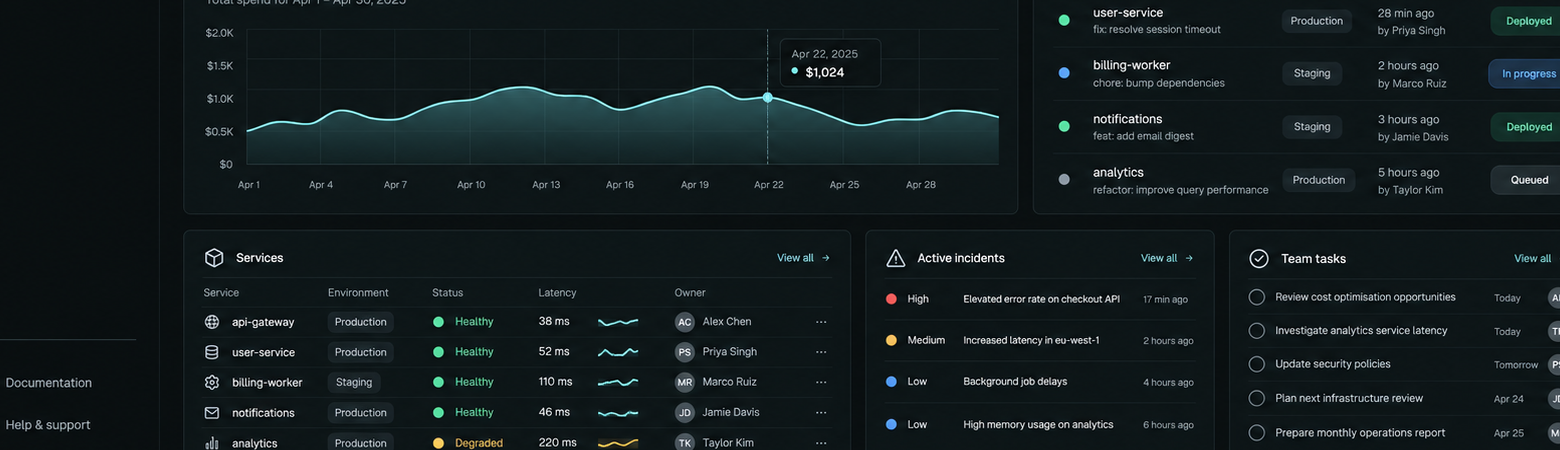
Distributed Trace Flamegraphs & Autonomous Remediation Queue
A microscopic view into the distributed tracing and incident triage queue. SREs can inspect microsecond-level flamegraphs, correlate upstream microservice dependencies, and verify automated remediation receipts.
- check_circle Real-time distributed trace flamegraphs identifying slow database queries and thread deadlocks
- check_circle Automated canary rollback confirmation receipts logged to immutable audit streams
- check_circle AI root-cause synthesis correlating multi-region network anomalies with commit changesets
We bypassed traditional userspace log collectors by deploying lightweight eBPF probes directly into the Linux kernel. This allows StationOps to inspect TCP retransmissions, socket buffer drops, and memory allocation churn in under 30 milliseconds with less than 0.5% CPU overhead.
When an anomaly signature is detected—such as a memory leak trajectory in a canary release—the autonomous remediation engine triggers a Temporal workflow. The workflow isolates the failing pod, gathers memory core dumps for post-mortem analysis, and rolls back ingress traffic safely.
Core Production Stack:
7-Stage DAG Architecture Blueprint
Live signal pulses tracing data ingress through classification, parallel branches, and persistent storage
Measurable Impact & Concrete Business Returns
Every line of code delivered for stationops was engineered to eliminate systemic bottlenecks, reduce infrastructure spending, and accelerate business throughput without vendor lock-in.
| Architectural Metric | Pre-Existing Legacy Monolith | Generic Solution Engine |
|---|---|---|
| Critical Incident MTTR | 4.2 hours average downtime | 38 minutes automated autonomous resolution |
| Nightly On-Call Paging Alerts | 400+ noisy alerts per week | Reduced by 91% through autonomous self-healing |
| Canary Rollback Speed | 45 minutes manual rollback ceremony | Under 90 seconds automated eBPF rollback |
| Monthly Cloud Spend | $420,000 with 45% idle capacity | Saved 38% via autonomous FinOps right-sizing |
100% IP Ownership
Full source code, Git history, Terraform state, and Docker containers transferred to your enterprise GitHub organization. Zero licensing fees or royalty locks.
Enterprise Security Standards
Audited for SOC-2 Type II, HIPAA BAA enclaves, and GDPR Article 32 compliance with mathematically verified cryptographic audit trails.
10-Day Production Kickoff
Senior engineering pods embedded into your Jira, Slack, and GitHub workflows within 10 days of alignment.
"StationOps gave us complete peace of mind. Our engineering team went from firefighting Kubernetes outages in the middle of the night to shipping code with 99.999% uptime."
Deploy an architecture like stationops for your enterprise.
We construct production software platforms with zero technical debt, 100% intellectual property transfer, and deterministic high-availability performance.